Hyrax 1.18.0 is now available.

Read the release notes →


Optimizing Xarray Dataset generation when working with multiple URLs
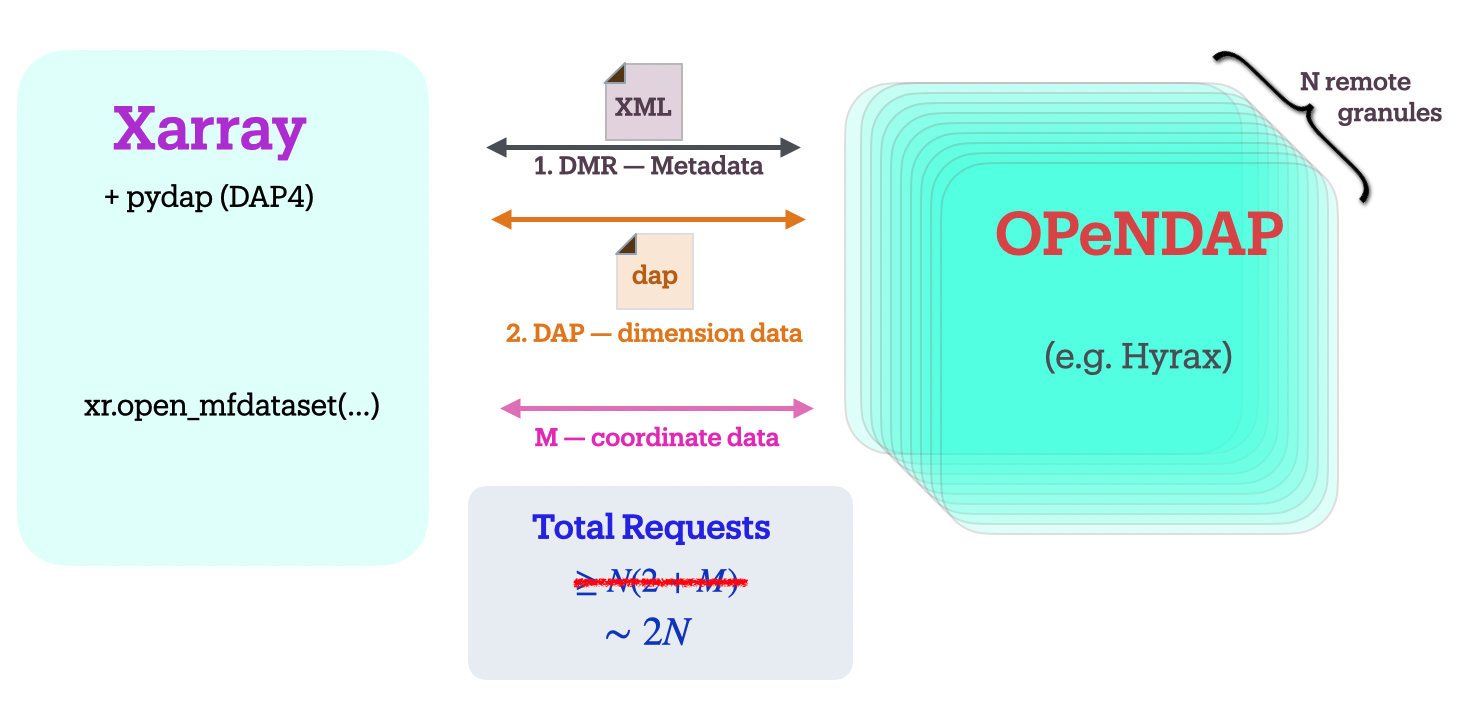
In a previous post, I showed that creating an aggregate dataset with Xarray from many (e.g., hundreds of) OPeNDAP URLs can become very slow because of unnecessary data requests, making it a real barrier to reproducible workflows and scientific discovery. Here, I outline a few ways to use the DAP4 protocol and Constraint Expressions to significantly accelerate dataset generation. This post applies to gridded data in which all remote files share identical spatial dimensions and coordinates.
A Constraint Expression (CE) is the OPeNDAP server’s native query language.
A CE is a collection of query parameters added to the OPeNDAP URL that tell the remote server what you want (as opposed to what you don’t want). Its syntax is as follows:
Python
base_opendap_url = "https://..."
# Below a Constraint Expression is appended
base_opendap_url + "?dap4.ce=/var1;/var2;/var3"
where base_opendap_url points to the remote source, and anything after "?dap4.ce=" specifies the variables of interest. In DAP4, variable names are written as absolute paths to avoid name collisions between variables in different groups.
Why not use Xarray drop methods?
Xarray can only drop a variable after it has been created, and sometimes only after its data has been downloaded. A Constraint Expression (CE) works the other way around: it tells the remote server up front which data you want, so nothing unnecessary is ever requested.
Aggregating Level 4 data via Xarray + PyDAP
We will work with DAYMET data and PyDAP to accelerate the dataset generation. The approach does the following:
- Drop all spatial coordinates and dimensions from all data URLs except the first data URL. Xarray can reuse the downloaded coordinates.
- Request only the variable of interest (precipitation), and the concatenating dimension (in this case
time), in all URLs.
The two steps above will result in a much faster data aggregation. Below we demonstrate with a reproducible example.
1. Create an isolated environment and launch a Jupyter notebook
Terminal
$ mamba create -n opendap_env -c conda-forge python=3.12 ipython pydap jupyterlab earthaccess netCDF4 xarray dask
$ mamba activate opendap_env
$ jupyter lab
2. Import necessary libraries
Python
import xarray as xr
import datetime as dt
import earthaccess

# import pydap-specific tools
from pydap.net import create_session, open_url
from pydap.client import get_cmr_urls
3. Access precipitation data from DAYMET
We will generate a dataset aggregation from 11 years of precipitation data from DAYMET in the Continental US. The temporal range is:
- Time range: 05/15/2014 - 05/15/2024.
Python
daymet_ccid = "C2531982907-ORNL_CLOUD"
time_range = [dt.datetime(2014, 5, 15), dt.datetime(2024, 5, 15)]

cmr_urls = get_cmr_urls(ccid=daymet_ccid, time_range=time_range, limit=1000)

prcp_na_urls = [url for url in cmr_urls if url.split(".nc")[0].split("Daymet_Annual_V4R1.daymet_v4_")[-1].startswith("prcp_annttl_na")]
The last line filters the URLs returned by CMR to keep only annual precipitation totals (prcp_annttl) over North America.
4. Authenticate with EDL via earthaccess
Python
from earthaccess.exceptions import LoginStrategyUnavailable
try:
    auth = earthaccess.login(strategy="netrc", persist=True)
except LoginStrategyUnavailable:
    # you will be prompted to add your EDL credentials
    auth = earthaccess.login(strategy="interactive", persist=True)

# Create a requests-cache session
my_session = create_session(session=auth.get_session(),use_cache=True, cache_kwargs={"cache_name":'debug_case'})

# If you do not want to cache the GET requests for debugging, do instead:
# my_session = create_session(session=auth.get_session())
5. Use Constraint Expressions to reduce variable and requests count
Here, we use PyDAP to inspect the metadata of a single remote file and identify the variable of interest, along with its dimensions and coordinates. We then use this information to minimize the data downloaded, which speeds up dataset creation considerably. The steps are:
- From a single data URL, identify the variable of interest and all its dimensions and coordinates.
- For the first URL only, use a CE to request the variable of interest, the concatenating dimension (
time), and all spatial dimensions and coordinates. - For all remaining URLs, use a CE to request only the variable of interest and the concatenating dimension.
- Combine all URLs into a single list of modified DAP4 URLs.
These steps rely on a useful property of Xarray: when combining files, it reuses the spatial dimensions and coordinates from the first file for all others, as long as their names and sizes match.
Python
# Inspect a single remote file
pyds = open_url(prcp_na_urls[0], session=my_session, protocol="dap4")

# 1) Identify variable of interest and all its dimensions and coords
Variable = "/prcp"
dims = pyds[Variable].dims
coords = [coord for coord in pyds[Variable].attributes["Maps"] if coord not in dims]

######=============================
# Optimizing the number of requests below is code that minimizes what data is downloaded when generating  an Xarray Dataset.
#####==============================

# ========
# 2) Keep all coords and dims of precipitation in first URL
url1 = prcp_na_urls[0].replace("https", "dap4") + "?dap4.ce=" + ";".join(dims+coords+[Variable])


# ========
# 3) For rest of URLs, drop spatial dimensions and coordinates
urls_rest = [url.replace("https", "dap4") + "?dap4.ce=" + ";".join(["/time", Variable]) for url in prcp_na_urls[1:]]


# ======
# 4) Final list of OPeNDAP URLs
urls = [url1]+urls_rest
6. Create an aggregate dataset
Python
# clear the cached URLs to check how many responses are downloaded
my_session.cache.clear()

# Xarray Dataset Generation
ds = xr.open_mfdataset(
    urls, session=my_session, engine="pydap",
    parallel=True, concat_dim="time", combine="nested",
)

print(len(my_session.cache.urls()))
The print statement returns 22 URLs (2 × N, with N = 11 files): one metadata request and one data request per file. This is optimal!
What if you skip these optimizations?
Due to a very important default safety feature in Xarray (discussed in this post), Xarray will download all spatial dimensions and coordinates from each file. Our optimization above made use of the fact that these spatial coordinates and dimension arrays are identical, so these were "pre-dropped" from all but the first URL.
You can measure the performance gain by running the following code with no optimizations, which uses the original URLs
Python
# new session that does not cache - write times can be significant. But first, inherit credentials
other_session = create_session(session=auth.get_session())

# take original list of URL and make them DAP4 URLs
dap4_urls = [url.replace("https", "dap4") for url in prcp_na_urls]

# Xarray Datset Generation
ds = xr.open_mfdataset(
    dap4_urls, engine="pydap",
    session=other_session,
    parallel=True, concat_dim="time", combine="nested",
)
The above snippet of code will take minutes to complete!
To verify all the extra downloads use the requests-cache session object instead. This is, use "session=my_session" above, to the dataset generation, and print the cached URLs. (Do not forget to clear the cache before)
Verdict
Our optimizations reduced dataset creation from a few minutes to a few seconds. This a speedup of up to 60×.


